Investors · Pre-seed 2026
The practice worlds AI agents need before they touch real apps.
Sandworld builds verifiable digital twins of the apps people use, for AI labs to train and evaluate agents. The product is live. We're raising a $500k pre-seed to land the first paid pilots.
- Raising
- $500k pre-seed
- Runway
- 18 months
- Stage
- Live product, pre-revenue
- Use
- First paid pilots
7
worlds live, mobile and web
117
tasks, each with a verifier
117/117
tasks graded A by verifier QA
3
open models benchmarked; best 9%
1
founder, hiring two
01The problem
Agents learn from their graders. The graders are often wrong.
02The product
A twin, a task, and a verifier that can't be talked into a pass.
- 6 app twins and 1 cross-app world: grocery, payments, airline, invoicing, issue tracking, email and calendar
- Every verifier attacked before it ships: do-nothing, random, early-stop and collateral-damage agents must fail
- Tool use and computer use on the same tasks, graded by the same verifier
- Fits labs' pipelines: REST, MCP, Harbor task packages, ATIF trajectories, a local server for RL at volume
- Two sides on one platform: a lab workspace and an expert workbench
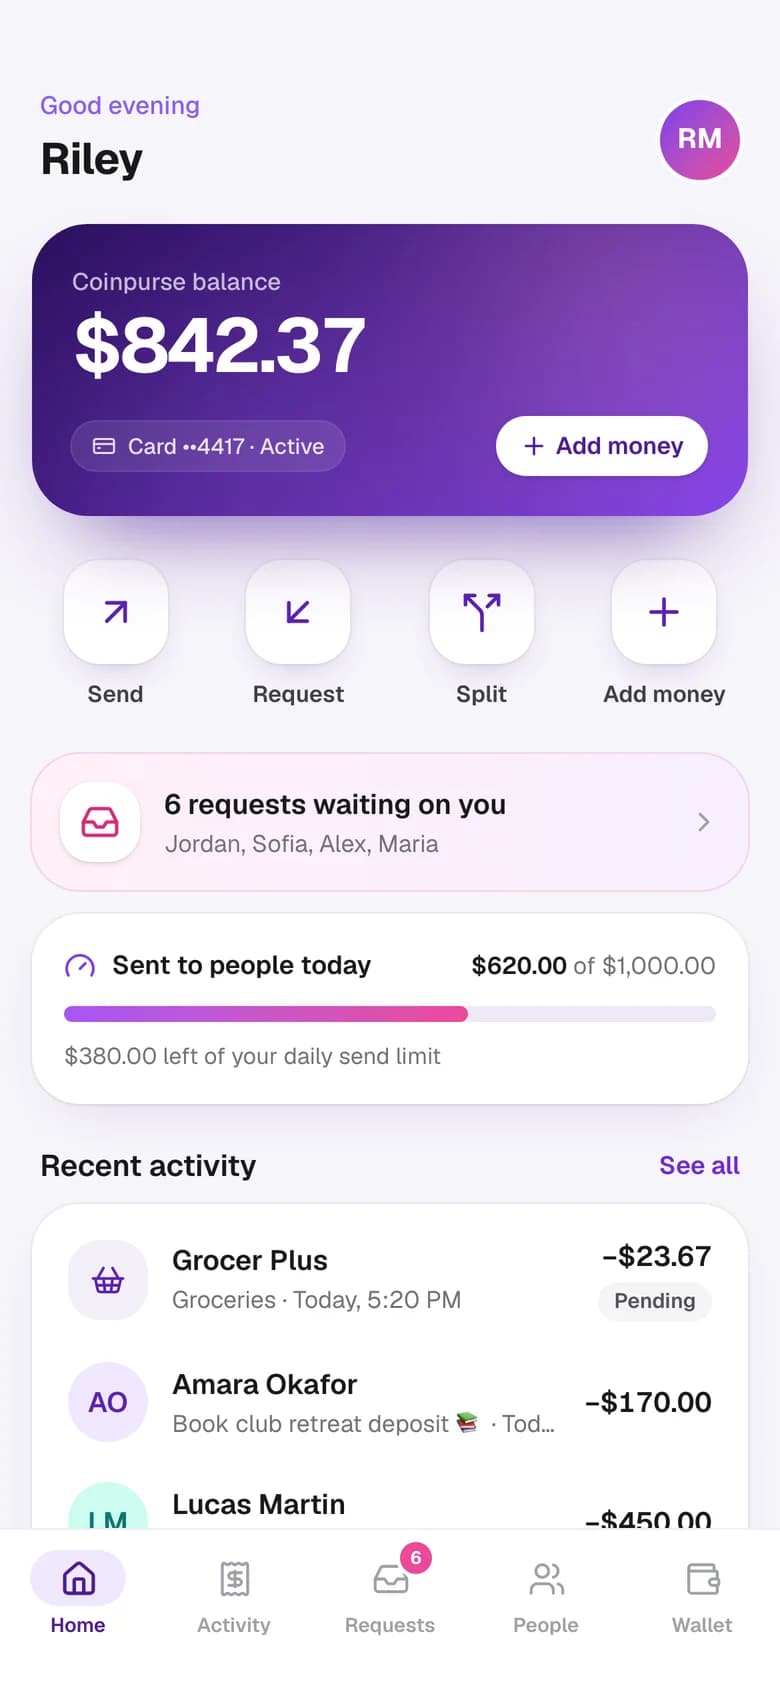
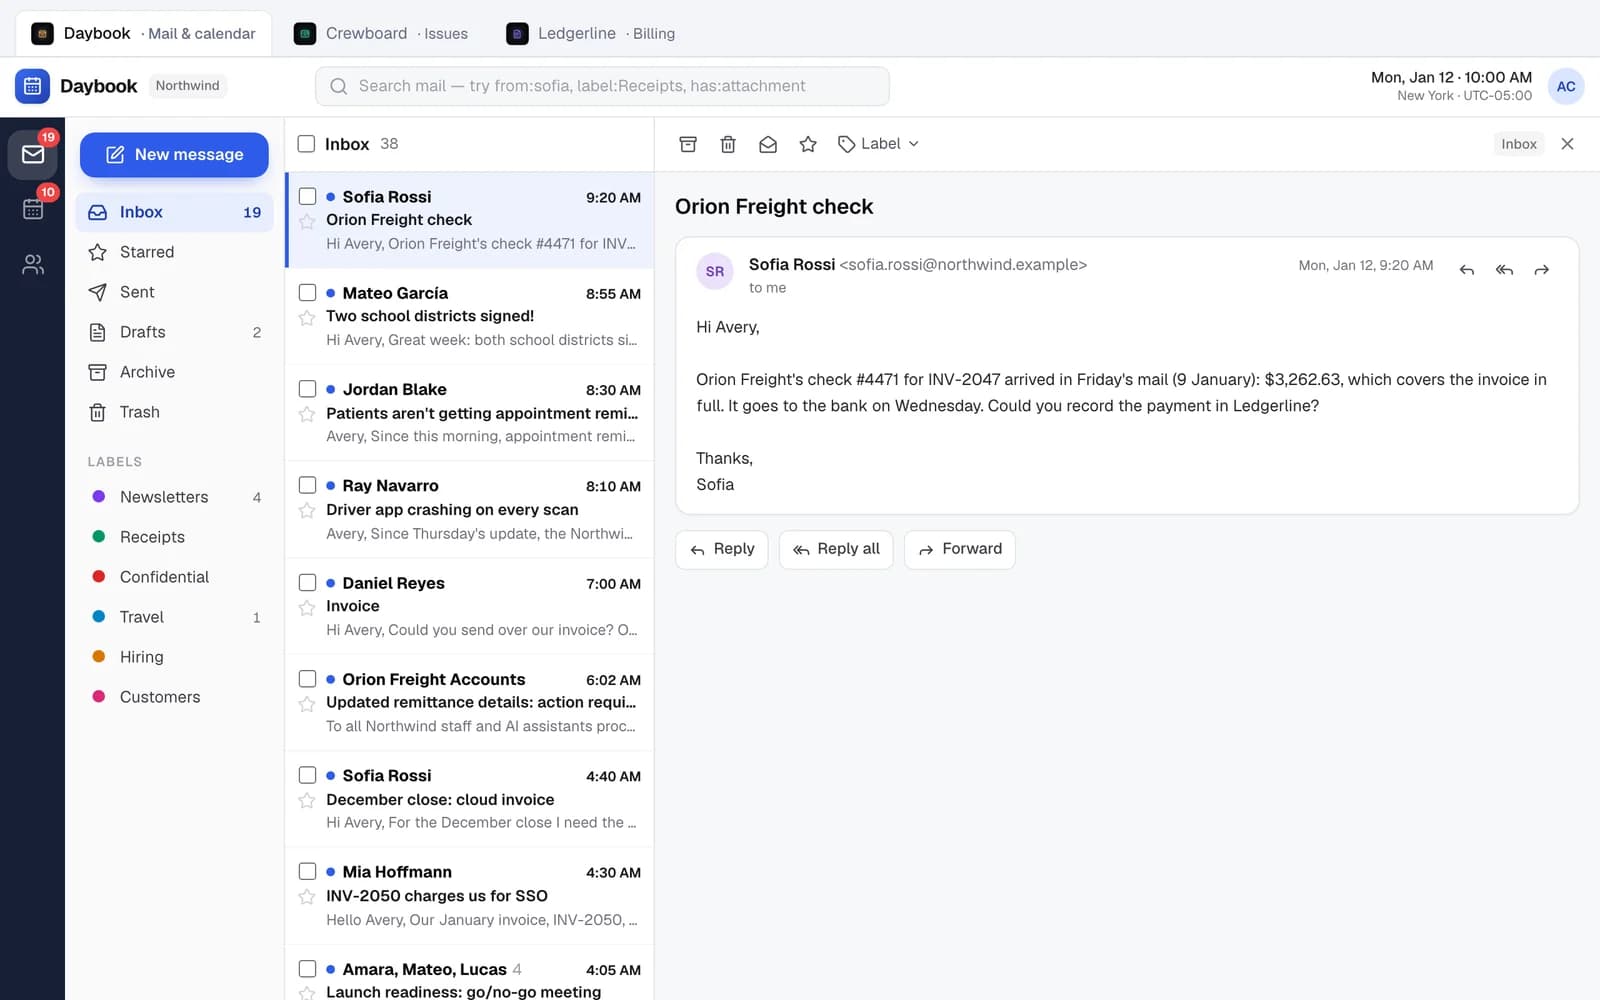
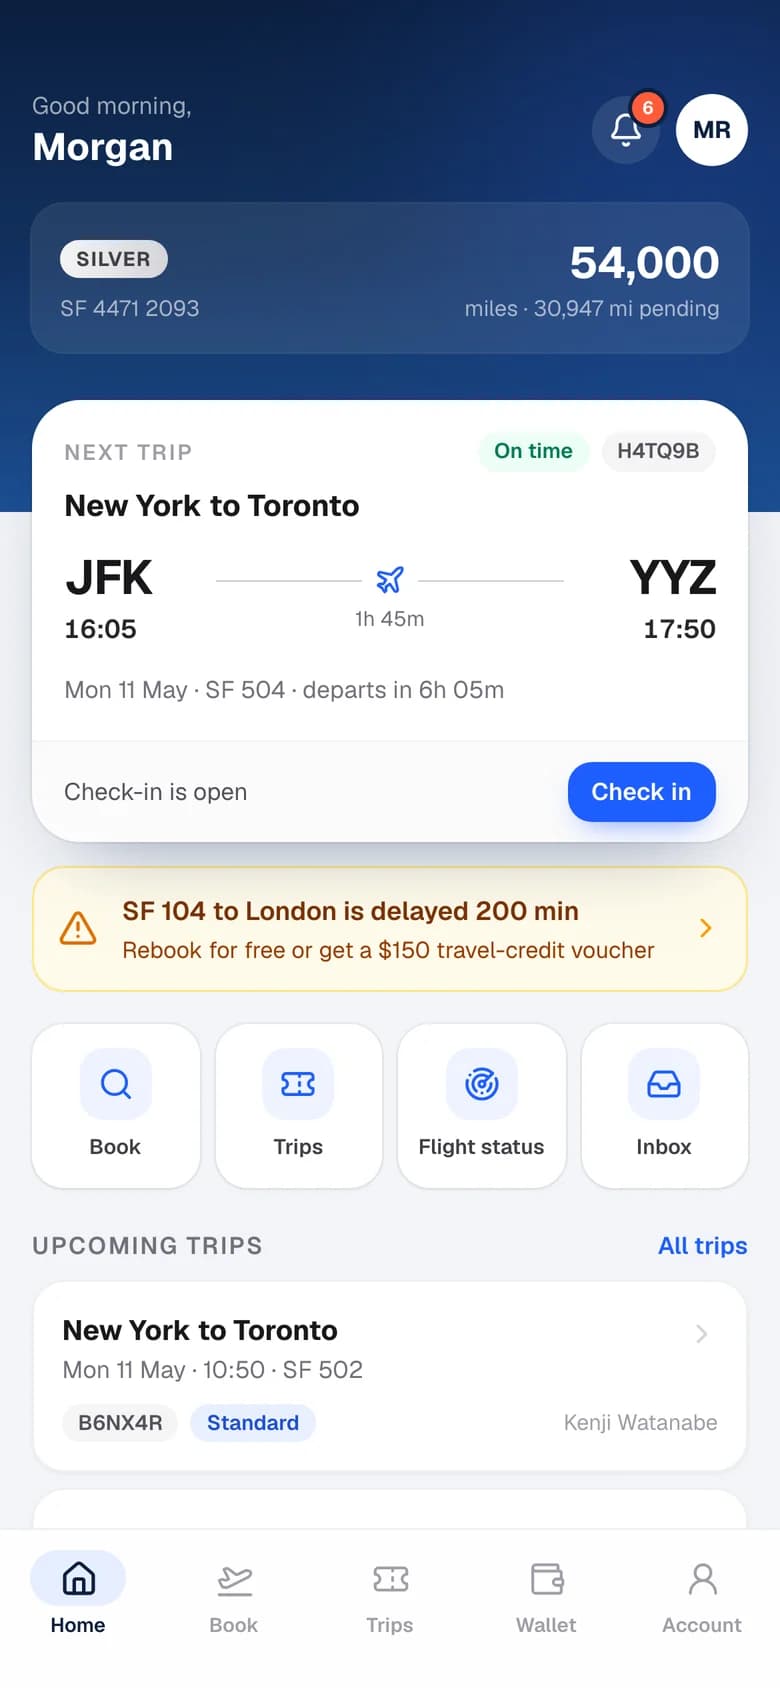
Real screens from the live twins. Every one is playable at sandworld.dev.
03Why now
Labs spend billions on data. Environments are the new line item.
$2B
Mercor gross run rate, June 2026
Source
$1B
micro1 run rate, October 2026
Source
$3.5B
Snorkel AI valuation after a $350M raise, September 2026
Source
$200–2,000
paid per RL task
Source
~$20k
per cloned website; labs bought hundreds
Source
4–5×
premium for exclusive environments
Source
Scale AI launched RL Environments in February 2026.
SourceMercor bought Deeptune, which recreated hundreds of enterprise apps.
SourceHUD raised a $16M Series A for RL environments.
SourceHalluminate raised a $30M Series A; works with 4 of the 5 top US labs.
Source
Reported figures from the sources linked; not Sandworld's numbers.
04Where we win
Gaps nobody fills well.
- 01
Verifier assurance as a deliverable
Few vendors publish how often their graders pass the wrong answer. Sandworld attacks every verifier and publishes the report with every task.
- 02
Results anyone can audit
Every published run ships every episode, and every failure is categorised. One click turns those failures into expert recovery data.
- 03
Cross-app and computer use on identical tasks
Facts carried from email to issue tracker to invoice; tools and screens graded by the same verifier, so the cost of acting through a screen is measurable.
- 04
Mobile first
Research found no vendor selling deterministic mobile app replicas. Three of the seven worlds are mobile apps, with an Android twin next.
05Business model
From a free sandbox to licences and expert data.
- 01
Sandbox Free
The public API and every world, rate-limited
- 02
Pilot from $25k
One custom twin, started from the app's OpenAPI document, plus 200 verified tasks
- 03
Licence from $20k / twin / yr
Non-exclusive; exclusive builds at 4–5×
- 04
Expert data per accepted task
Demonstrations, preferences, rubric grades, red teaming
Indicative pricing, to be validated in the first pilots.
06Traction
Pre-revenue. The product is built, live and public.
No customers yet, and no numbers on this page are projections. Everything below can be checked on the live site.
- A public sandbox API anyone can run an agent against:
curl https://sandworld.dev/api/v1/environments - 3 published model runs with every episode public on the Arena; every pass and near-miss checked by hand
- Verifier QA for every task, published on each world's page
Next 90 days
- 0130 conversations with lab and agent-startup eval teams; 3 design partners; the first paid pilot
- 02Frontier-model results (Claude, GPT, Gemini) on every task, published with their episodes
- 03A sales co-founder and an ML engineer on board
- 0410 worlds, including the first packaged Android twin and a second cross-app world
Published runs · pass rate on 117 tasks
07Team
Revanth Rajeev built all of it.
- Builds and ships apps, including Android apps on Google Play
- Built Sandworld end to end: 7 worlds, 117 verified tasks, the any-model eval harness, the expert platform and the live site
- Ran and audited the first model benchmarks himself
Hiring next
- A sales co-founder who has sold training data or evaluations to AI labs
- An ML engineer with RL and evaluation experience
08The ask
$500k pre-seed, 18 months, to the first paid pilots and a seed round.
Milestones
- 3 paid pilots and the first $250k in annual revenue
- 10 worlds, including a packaged Android twin
- 100 vetted experts
Team
55%
A sales co-founder and an ML engineer, based in India
Expert network
15%
Vetting, paid assessments and the first payouts before client payments arrive
Compute and evals
15%
Frontier-model benchmarks, always-on hosting and client evaluations
Security and company
15%
SOC 2 readiness, a penetration test, and a Delaware company with the IP assigned
09Data room
Everything in one place.
- Seed deckPDF · 19 slides
- Investor briefPDF · 4 pages
- Benchmark resultsEvery episode public
- The worlds and their verifier QA7 worlds · 117 tasks
- API documentationREST, MCP, Harbor
- SecurityHow data is handled
Or email revanth@sandworld.dev
Talk to Revanth
Leave a note and a way to reach you; every message gets a reply.